Take a typical online order. It’s placed, paid for, the delivery address is changed, it ships, and it arrives. Now look at how most systems store that. A single row ends with status = "Delivered", and every earlier version of the row has been overwritten. You can see where the order is now, but you can’t see how it got there.
That’s the built-in limitation of the CRUD (Create, Read, Update, Delete) model: each update replaces the previous state. Event sourcing works the other way round. You never overwrite anything. Each change is appended as a new, immutable event, and the current state is whatever those events add up to. A bank statement is a good comparison: it lists every transaction, not just today’s balance.
Serverless AWS services fit this model well. DynamoDB, Lambda and EventBridge are already event-driven and scale on demand, and you pay only for what you use. In this post I’ll explain what event sourcing is, show a reference architecture on AWS, and go through when it’s worth the extra complexity and when it isn’t.
The core idea is simple: store events, and derive state from them. Here’s the same order in both models:
| CRUD model | Event-sourced model | |
|---|---|---|
| What’s stored | One row: status = "Shipped" |
A timeline: OrderCreated → OrderPaid → OrderShipped |
| How updates work | Overwrite the row in place | Append a new event |
| Current state | Read the row | Replay (fold) the events |
| History | Lost unless you build audit tables | Kept by default |
You can always rebuild the current state by replaying an order’s events. The real value, though, is in the history itself, because it answers questions a CRUD table can’t:
So the database becomes a record of everything that has happened, not just a snapshot of the present. You can replay that record to rebuild views, feed analytics pipelines, or power features nobody had planned when the events were first written, all without touching the original data.
A CRUD table tells you where your system is. An event log tells you the whole story of how it got there.
Any event-sourced design has to answer two questions: where do the events live, and who consumes them?
DynamoDB is a common choice for the event store on AWS. Event payloads differ by type and tend to change over time, and a schemaless table handles that easily. Every change in the system becomes a new item, appended and never updated.
Enable DynamoDB Streams on the table, and each new event can trigger a Lambda function. That consumer reacts in near real time, for example by updating a view, sending a notification, or forwarding the event to a bus such as EventBridge.
Here’s the end-to-end flow. Clients submit events through a REST API on API Gateway. The API appends them to the DynamoDB event store, and each new item flows through the stream to the Lambda consumer.
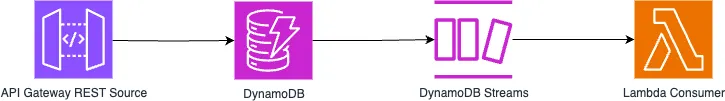
This design has a problem. The event store holds a sequence of changes, not a final state. To answer something as basic as “what’s the current status of this order?”, you’d have to load and replay every event for that order, and do it again on every request. That’s slow and costly.
CQRS (Command Query Responsibility Segregation) fixes this by separating the write path from the read path:
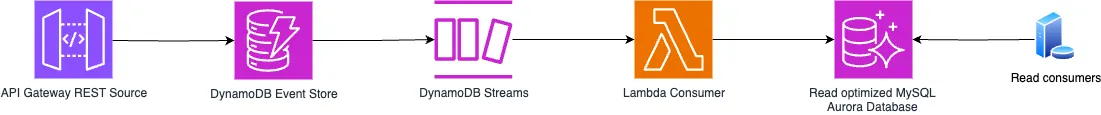
To clients, this read model (often called a projection) looks like an ordinary transactional database: quick to query and easy to use. Meanwhile the event store keeps the complete history. The event store records what happened, and the projection tells you the current state. Together you get full traceability and fast reads.
The diagrams leave out a few things that make the difference in a real system:
Query, and the events come back in order.(aggregateId, version) item doesn’t already exist. If two requests race to append version 5, one of them fails cleanly instead of silently creating a conflicting history.
The main benefit is a built-in audit trail. Because no event is ever deleted or modified, you always know what changed, when, and who changed it. That’s a big advantage in regulated areas such as finance, and it makes compliance checks, debugging and forensic investigations much easier than with a table that only keeps the latest value.
Because the log is immutable, you also get replay and recovery for free. If a projection gets corrupted, or you ship a bug that wrote bad data into it, clear the projection and replay the event stream to rebuild it.
You can also run temporal queries. A CRUD table can only tell you the state now. With an event log you can ask what an order looked like yesterday at 3 PM, or follow how it changed step by step.
It also helps when requirements change. A new feature often needs the data viewed in a new way. Instead of migrating a schema, you create a new projection and fill it by replaying the events you already have. The system grows without rewriting its history.
Finally, it fits naturally with event-driven architectures. Events can be published to Amazon EventBridge and consumed by any number of independent services, none of which needs to know about the others.
None of that comes free. Before you commit, weigh these trade-offs carefully.
You’re taking on more moving parts. Storing, ordering and replaying events needs more infrastructure than a CRUD table, and you have to plan for serialization, versioning and schema evolution from day one. Storage keeps growing, because immutable events pile up forever unless you use snapshots or a compaction strategy. Reads become eventually consistent: projections are updated asynchronously, so they can briefly lag behind the latest write, and the rest of the system has to tolerate that.
There’s a human side too. Debugging is harder when the cause of a problem is spread across a long chain of events instead of a single row you can inspect. And there’s a real learning curve for teams used to CRUD, because thinking in events takes practice.
In short, the auditability, traceability and replay are real benefits, but you pay for them in operational overhead and design effort.
| Event sourcing is a good fit when… | Stick with CRUD when… |
|---|---|
| You need a complete, immutable record of every change (banking, healthcare, heavily regulated domains) | The domain is simple and CRUD already meets your needs |
| Past states drive business decisions, such as dispute resolution, fraud detection or analytics | Running an event store, replay logic and projections would cost more than it gives you |
| You need to scale out horizontally under heavy load | The team doesn’t yet have experience with distributed, event-driven systems |
| You’re already using CQRS, projections or event-driven microservices | |
| You want to keep raw events so future features and analytics can use them |
Event sourcing also doesn’t have to be all or nothing. You can apply it to the one bounded context that really needs a history, such as payments or orders, and keep the rest of the application on plain CRUD.
Is event sourcing the same as CQRS? No. Event sourcing is about how you store state, as a log of events. CQRS is about separating the write model from the read model. They’re often used together, as in this post, but you can use either one without the other.
Is EventBridge my event store? No. EventBridge is a bus for distributing events to other services. It isn’t a durable, queryable history you can replay per aggregate. Keep the event store in a database such as DynamoDB, and publish to EventBridge from your consumer.
How do I fix a wrong event?
Don’t edit it. Append a compensating event (for example, PaymentRefunded or AddressCorrected) so the history shows both the mistake and the correction.
Event sourcing changes the question from “what is the state?” to “what happened?” Storing every change as an immutable event gives you auditability, flexibility and scalability, and that suits cloud-native systems on AWS. It also brings challenges, including event ordering, schema evolution and operational complexity, so it needs careful design.
Used in the right place, such as systems that need strong audit trails, point-in-time reconstruction or real-time insights, it can make your applications much more reliable and adaptable. Don’t use it to replace CRUD everywhere. Pick the model that fits each problem. When event sourcing does fit, combining it with CQRS and building on DynamoDB, EventBridge, Kinesis and Lambda gives you an event-driven system that’s resilient and ready for whatever you need next.